Robot-Use Agents: When Frontier Models Leave the Screen
In brief
In brief
Robot-use agents observe a robot, call its skills and do checks of the result. They can select better tool sequences during a task. They can also make code and policies better across verified trials. Separate roles continue to be necessary for planning, permission checks, fast control and hardware protection.
- Agents can select existing skills and do checks of them, or make them better across trials. They can execute only physical skills available in their tools.
- Grounded robot trajectories may make text-centric reasoning better. The robot benchmarks discussed here do not include a test of this training hypothesis.
- Keep planning, permission checks, fast control and hardware protection separate. Better proposals alone cannot prevent unsafe motion.
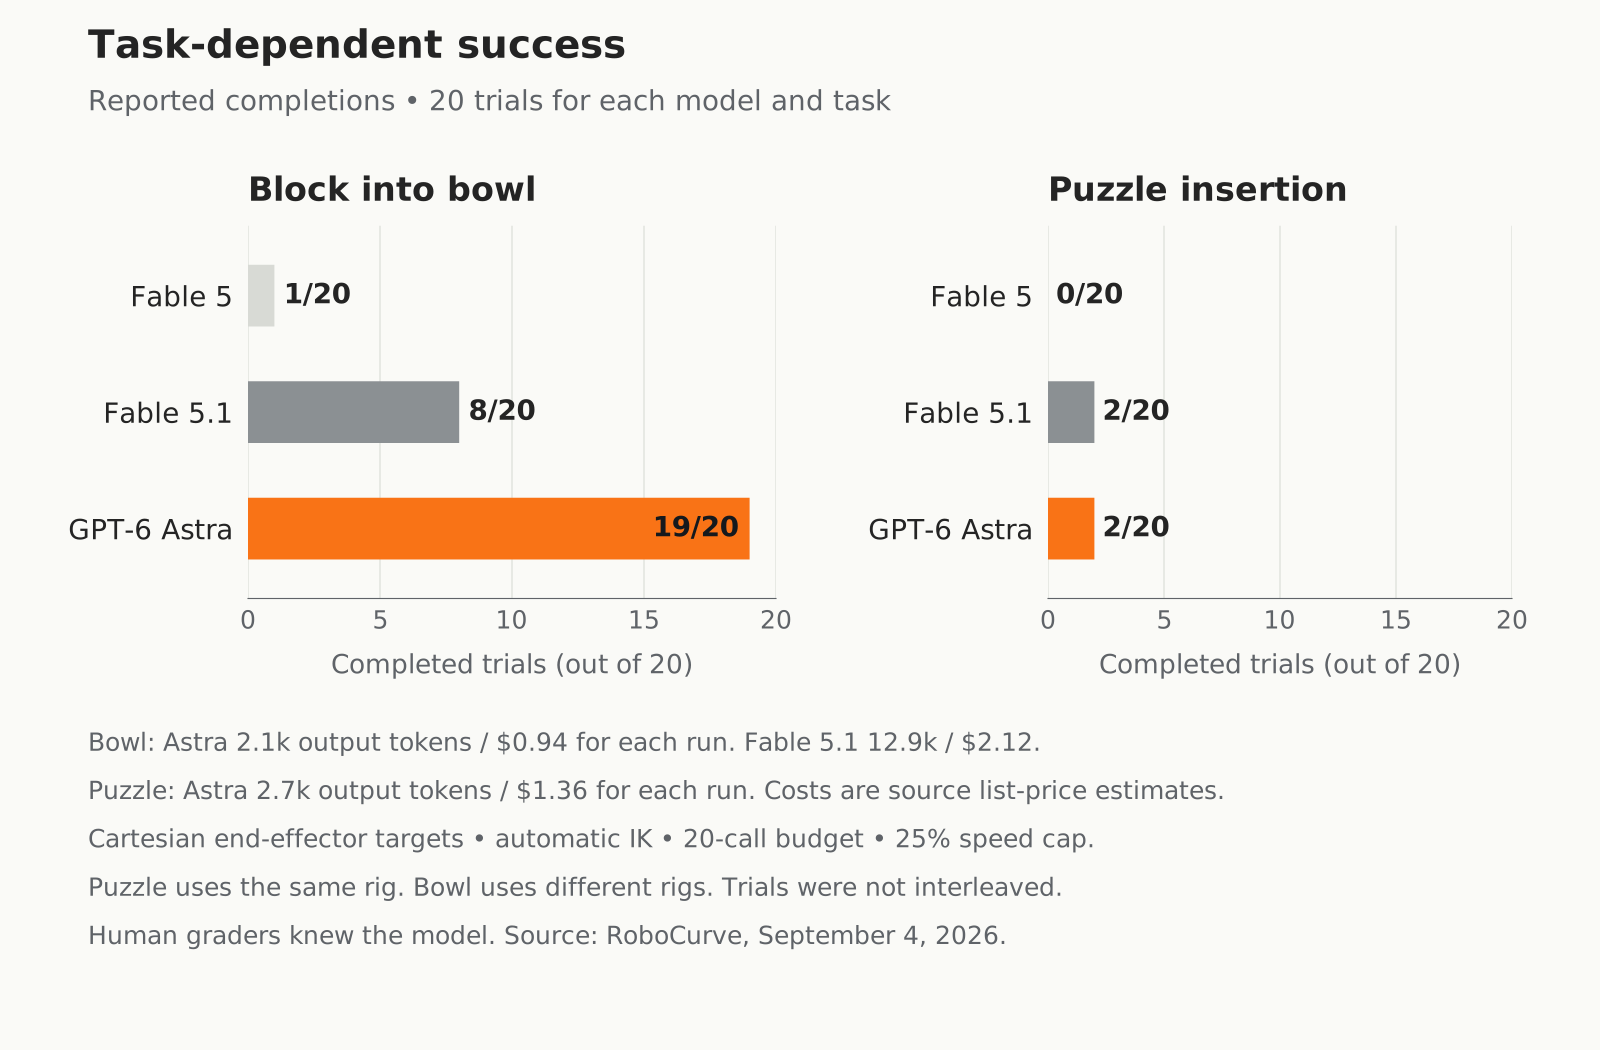
One robot benchmark gave two numbers that look as if they came from different eras. In a September 2026 RoboCurve evaluation (see also Jay Chooi's benchmark thread), GPT-6 Astra put a red block in a bowl in 19 of 20 trials. On precise puzzle-piece insertion, it completed 2 of 20 trials—the same as Claude Fable 5.1. On the bowl task, Astra also used about 6.2 times fewer output tokens than Fable 5.1. Its cost for each run was less than half as much.
The same model can do a task when perception, geometry, and tolerance agree. But it can stop at the final millimeters of contact-rich manipulation.
The models observed three camera views and proprioception—the robot’s sensed body state. Then they sent requests for absolute end-effector poses. Automatic inverse kinematics (IK) converted poses into joint commands. All trials used bimanual YAM arms, the same instructions, a 20-call budget, and a 25% speed cap. The evaluation measures model-guided manipulation through that interface. Local machinery continues to supply robot control.
Frontier agents now start to divide tasks, select tools, write programs, do checks of progress, and recover. Other parts of the stack supply motion and protection. That division alone may change robotics.
I examine two questions: where the physical competence lives, and what changes during a task or across trials.
A robot as a tool
Phillip Isola's short essay gives the clearest framework: cameras and state supply observations. Navigation, grasping, and motion are tools. The agent becomes the robot's puppeteer. The word use changes the focus from a policy trained for one body. An interface lets a general agent attempt a task on an unfamiliar machine before a weight update from that experience.
An end-to-end vision-language-action (VLA) policy maps vision, language, and robot state to actions. A robot-use agent may call a VLA. It can also call inverse kinematics, a motion planner, a perception service, or generated code. The agent selects what to call. It does checks of the result and recovers when the world disagrees.
The lineage is familiar. SayCan chose among grounded skills, Code as Policies composed robot programs, and Inner Monologue replanned from feedback. Today's agents can also read unfamiliar APIs and examine images and traces. They can write code, do tests of it, and keep state across long tasks. Robotics research now examines the transfer of those software abilities.
Three control clocks
Robot control has three speeds. Seconds may be necessary for a multimodal agent to infer intent, track task state, or ask permission. A learned skill policy converts “grasp the mug” to poses or action chunks at roughly 10–100 Hz. Servoing and protection control force, balance, collision response, and emergency braking at hundreds of hertz or more.
The architecture must obey timing constraints. Semantic reasoning can be remote and deliberative. Physical data and a fast loop are necessary for contact recovery. Protection must continue to operate during network loss and model delay.
Key question
Examine which layer supplies each skill, and how quickly it can correct an error. RoboCurve's simple-task success rate increased, but insertion changed little. The tasks have different timing requirements.

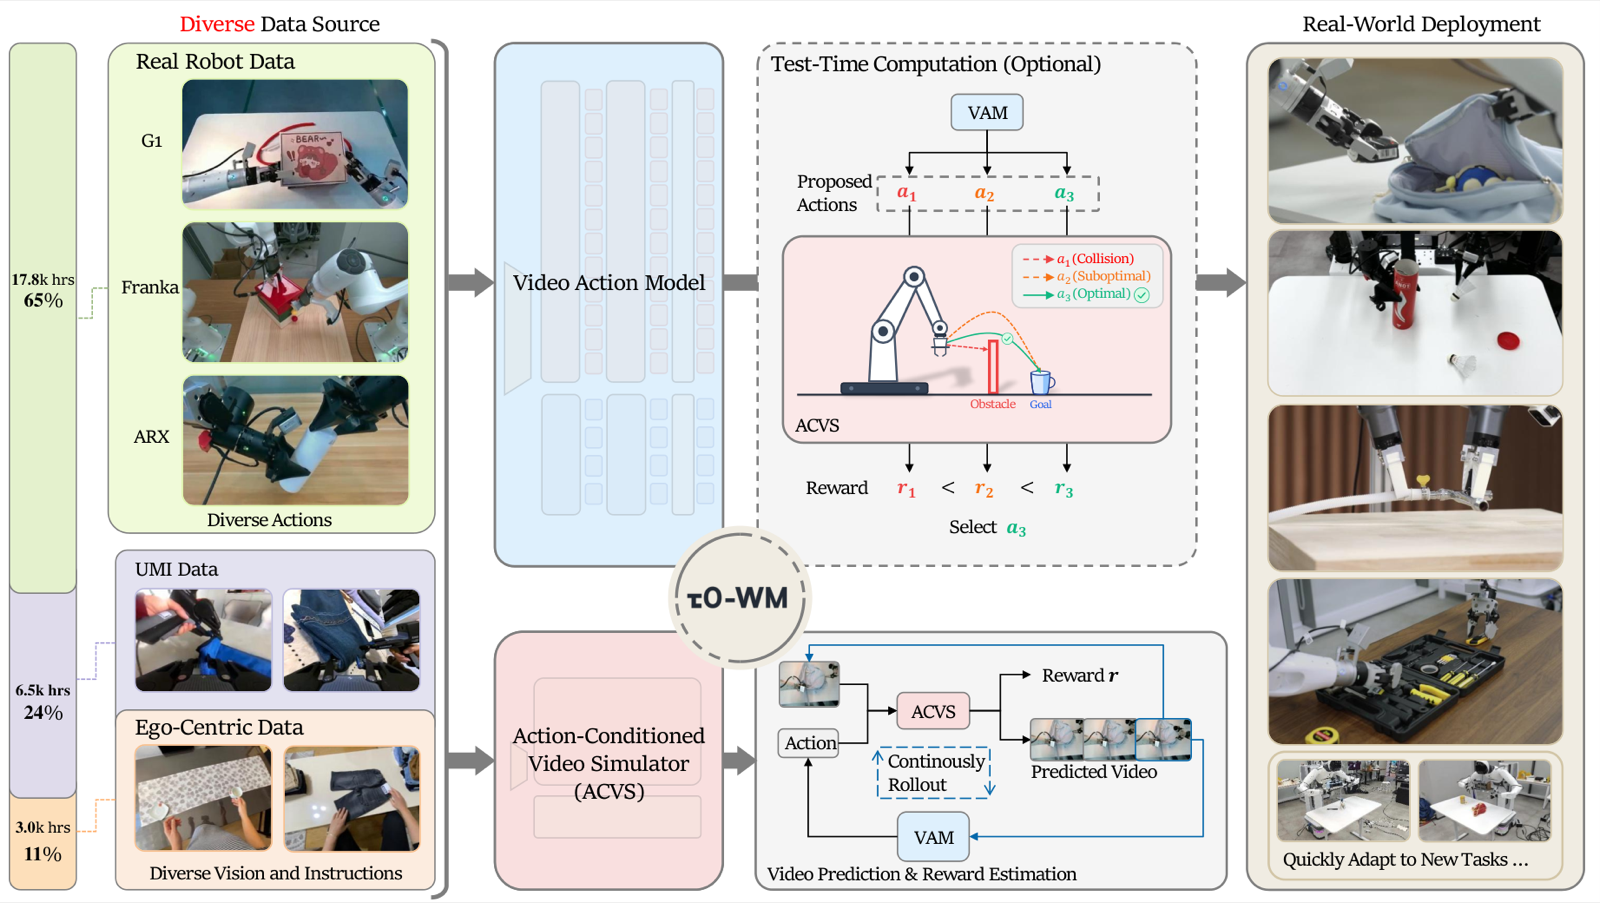
A robot system also has more methods to adapt to a new task. π₀ and later VLAs include more dexterity in learned action chunks. By 2026, agents compose tools and repair programs. Physical prompts put demonstrations in context. World-action models (models that predict future frames together with actions) use test-time compute for predicted outcomes. “No fine-tuning” can mean several different methods to adapt.

Where physical skills live and what can change
The clocks show how quickly each layer must respond. Now examine which part supplies the physical skill, and what changes when the system adapts. Systems can use these six routes together:
| Route | Where competence lives | What changes for a new task | Main limit |
|---|---|---|---|
| End-to-end VLA | Weights learned from heterogeneous robot actions | Observation-conditioned tokens, waypoints, or continuous chunks | Action data and embodiment support. Other machinery is necessary for planning and permissions. |
| Physical prompting | A physically pretrained policy plus a teaching trace | Demonstrations enter the current context. Optional fine-tuning changes weights separately. | Cross-body alignment, accidental demonstrated motion, limited scene coverage |
| World-action model | A learned action prior and predictor | Candidate chunks and predicted outcomes are sampled, ranked, and revised. | Plausible video can misjudge contact, friction, or hidden state. |
| Hierarchical planner | Learned skills and analytic primitives behind callable interfaces | Subgoals, backend selection, and recovery change during the task. | Skill ontology and the dexterity already available in the tools |
| Code as policy | Programs that use perception, IK, planners, and policies | The agent generates or repairs code. Validated routines can enter a persistent library. | Correct syntax can still hide incorrect transforms, stale perception, or unsafe recovery. |
| Visual-interface agent | Engineered views and a small action vocabulary backed by a controller | Targets and tool calls change after fresh observations. | Interface bandwidth and hidden controller competence |
A browser-controlled agent can call a VLA from generated code. That VLA can use a physical prompt, and a world model can rank its proposals. Learned components are still necessary for “training-free” operation. Identify the changed item: context, plan, program, candidate motion, skill library, or weights.
τ₀-WM shows the split. Its joint visual–action model and simulator supply learned skills. Test-time sampling and rectification change candidate motion within an attempt. They do not certify that real contact will agree with the prediction.

Why systems use planners and skills together
A frontier agent interprets a request and selects tools. A VLA controls continuous manipulation, and a geometric planner enforces exact constraints. A local controller supplies high-frequency motion. I see a lasting division of labor. Each layer has a different timescale, training data, and requirements.
Identify the agent’s possible observations and requests. Identify the permitted parameters, the success checks, and who can interrupt. These rules matter more than the model on either side. Software tools also have these permission and execution limits.
Vincent Sitzmann argues that computer-use ability may transfer because the loops have the same structure. The agent observes state, selects a tool, examines the result, and makes changes. The ability to write programs can also transfer. For robot APIs, skills to read an unfamiliar library, do tests of it, and change code are also necessary. Better visual reasoning, spatial grounding, and tool use can make behavior better without a new task-specific policy.
After I watched Astra operate simulators, Blender, and real robots, I changed how I frame an older argument: is multimodality itself necessary for intelligence? I now focus on the kinds of work multimodality makes available. A model can change a scene, examine a render and move an object. It can do tests of a controller and observe the result. Each task gives a grounded trajectory: images, state, actions, code, errors, and outcomes connected to what happened.
Those trajectories can make capabilities that seem purely textual better. A failed manipulation becomes a debugging trace. A successful Blender workflow becomes a reusable program. Visual differences supply supervision for planning and verification.
The result could be distilled into language, code, memory, or policy updates. I treat better text-centric reasoning as a hypothesis about these training environments. The robot benchmarks below do not include a test of that transfer. But they supply feedback that a task description alone cannot give.
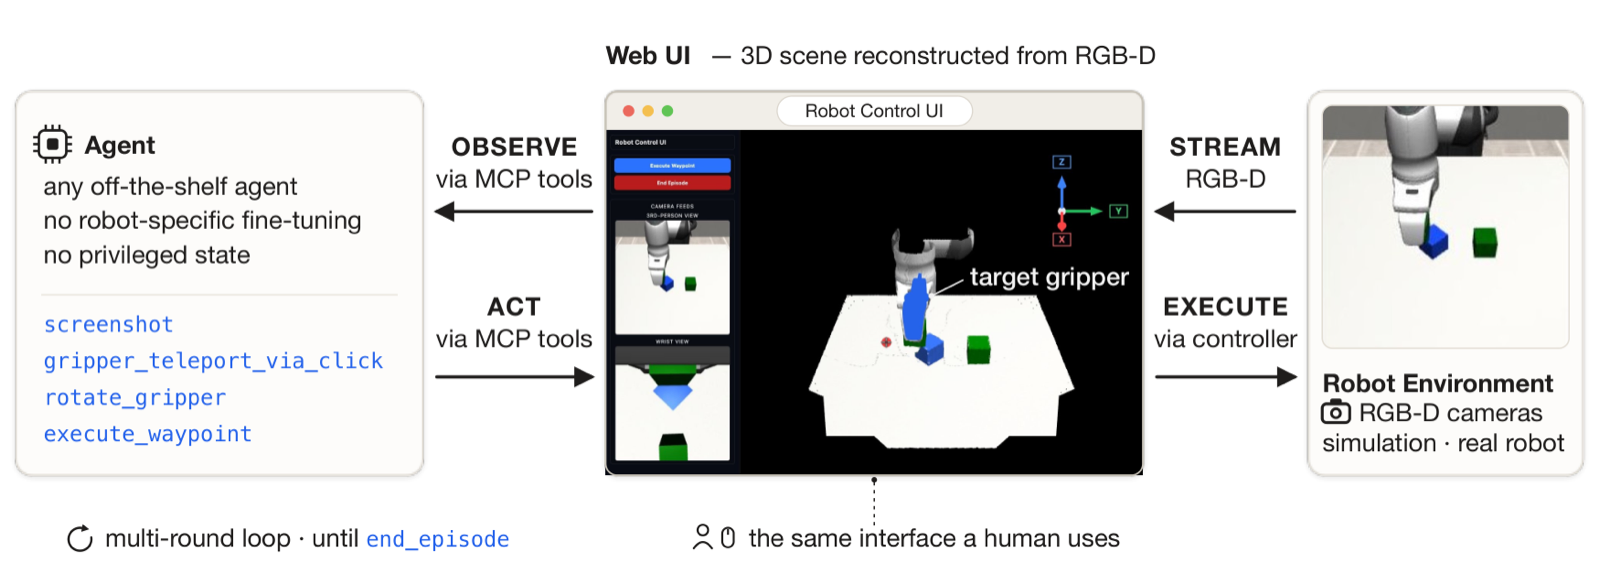
VIA makes the computer-use analogy literal. An off-the-shelf agent uses screenshots and a browser-based 3D interface without robot-specific fine-tuning or privileged simulator state. Its reported success is 96.7% across three LIBERO-Goal tasks and 100% on rainbow assembly. Point-cloud and camera views, Model Context Protocol (MCP) tools, a virtual gripper target, and a controller supply the contact loop. The agent itself does not learn that loop. The interface is part of the result.
Anthropic's Claude Plays Robotics gives the same conclusion across simulation, a real Unitree Go2, and manipulation. Models had problems with direct control of difficult joints. Their performance became better when they wrote controllers, steered pretrained policies, or used perception tools. CaP-X isolates the effect across twelve models, seven controlled tasks, and 100 trials for each tier. Higher-level abstractions, interaction, grounding, and more test-time compute all change performance.
Reading a robot demo
Include the tools’ contribution: IK supplies geometry, a VLA supplies robot data, and a planner supplies collision assumptions. Evaluate model plus interface plus execution budget. Do not attribute each skill to the foundation model.
Whether the transfer is “emergent” continues to be unknown. Proprietary training mixtures may contain robot code, simulation, trajectories, manuals, or benchmark-adjacent data. “No task-specific fine-tuning” gives information about the model at deployment. It does not give the source of its physical skill.
GEN-1.5 learns from demonstrations in context
Generalist's GEN-1.5 is a robot foundation model rather than a computer-use agent. It adapts at inference time. It accepts up to 30 seconds of video memory with language, proprioception, and other sensors, then emits trajectories at 100 Hz. A user can put a 3–12 second sensorimotor demonstration in that window while current observations continue. Generalist uses the name physical prompting for this input.
The prompt contains synchronized observations and actions. It is not only a video of the desired outcome. The prompt may come from handheld grippers or a robot rollout. The model must infer the intended motion, map it to the current scene, and correct deviations in closed loop. Language says what. The trace can show how.
The Generalist report gives 59% ±10% average success across ten simple, short-horizon tasks after one prompt and zero gradient updates. With about five minutes of task data—roughly fifty demonstrations—and ten gradient steps, the average increases to 83% ±9%. The comparison separates two changes. Prompting adds observations and actions to the current context. Optional fine-tuning changes weights.
Robot data continues to be central. Generalist says the model trained for more than eight months on a proprietary physical-interaction data engine. For a new task, broad pretraining may let a user configure a behavior the model almost knows, rather than train a new skill. Generalist selected the model, robot, tasks, demonstrations, and success criteria. Thus, this is a company evaluation, not an independent one. Generalist also says prompted skills stay more brittle than fine-tuned ones.
GEN-1.5 puts inference-time adaptation at a second layer. The semantic layer adapts through language, tools, memory, and traces. The sensorimotor layer adapts through action-bearing demonstrations and short gradient updates. A likely stack uses the two layers. An agent selects the goal and teaching signal, and a physically pretrained policy supplies responsive motion. Separate systems do checks of that motion and constrain it.
Two loops: during a task and across trials
Two loops change different things. During a task, the agent observes, selects a subgoal and calls a tool. It does checks of the outcome and uses available skills for recovery. Across verified trials, it can change a program, graph, library, training recipe, or policy for the next attempt. The two loops can increase success but change different parts of the system.
Frozen competence, a better execution path
OpenETA (OpenETA is the ETA paper's released system) shows the small-interface end of the first loop. Its Codex configuration supplies observe, mark_point, and move_to. Fresh observations are necessary after a world-changing call. The planner changes its targets and decisions. Perception, projection, gripper behavior, and local control execute the physical action. Pass@5 counts a task as solved if any of its first five seeds succeeds.
OpenETA has different rates for task coverage at Pass@5 and repeated episode success. It is easier to find one successful composition than to execute it reliably.
Pigey isolates the complementary case with learned motion. A frontier vision-language model (VLM) routes short subgoals to a frozen π₀.₅ or a task-and-motion-planning (TAMP) grasp planner, does checks of the result, and recovers. With the same frozen π₀.₅-LIBERO weights, mean success across six perturbation suites rises from 12.8% to 53.3%. The system changed its execution path at inference time, but its learned dexterity stayed fixed. Backend support is necessary, and occlusion can still fool the verifier. Frontier calls also add latency and cost.
Harness VLA follows the same pattern: refresh the object estimate and reposition around a frozen contact skill. These systems belong on the slower clock because they select skills and do checks of them. They cannot supply a grasp that no available backend can execute. The detailed benchmarks and hardware scope appear in the appendix.
A failed run becomes a reusable repair
Executable code gives the second loop an artifact for inspection. CaP-X does tests of programs that use robot primitives. ASPIRE records traces, repairs failures, does checks of the fix, and keeps procedural knowledge. Waddle's LEGO example goes a step further. It collects trials and trains an Action Chunking with Transformers (ACT) policy. That changes learned weights as well as the program.
GaP uses a computation graph assembled from a substantial initial skill library, so that scaffold also contributes to its gains.
The difference shows the artifact that a success leaves. A good retry solves the current episode. A validated routine may help a subsequent episode. A policy update can change the motor behavior itself.
Keep a repair only after it passes two checks: it corrects the original failure, and it continues to operate outside that one trace.
Physical experiments change the next policy
ENPIRE makes the experimental loop explicit. Human feedback first helps to construct safety, reset, and verification APIs. Those APIs then stay fixed while coding agents do tests of heuristics, tool calls, training code, or policies and change them. A trial supplies reward and logs to the agent, which changes the candidate for the next trial. Here the next trial uses a changed candidate, rather than only a better subgoal for an unchanged VLA.
The repeatable environment is part of the learning method. A bad reset changes the experiment. A false success changes which candidate is promoted. More robots can do tests of hypotheses faster. But the paper gives information about underused hardware while agents read or write code, and disproportionate token cost as fleets grow. Physical experiments use a budget of resets, time, wear, and verification.
Gemini Robotics ER 2 places embodied reasoning above motor execution. The comparison with the systems here is about placement. A reasoner can direct the currently available tool. A research loop can make that tool better for subsequent operation.
Fig. 10 compares these placements as system paths: where adaptation happens, where feedback goes, and where physical competence stays.

Together, these systems show that general agents can do robot tasks without end-to-end learning of each task. Robot-specific learning continues to be essential. Four changes make this possible now.
Physical priors are broader: multi-robot and human-interaction data decrease how much motion each new task must teach. Action representations are more forgiving: continuous chunks keep coordination across joints, while Cartesian poses and typed skills trade bandwidth for easier reasoning. Embodiment integration and contact coverage continue to be necessary for these two gains.
Test-time compute is now part of the physical loop. A system can sample trajectories, predict futures, examine a visual difference, call a different tool, or reason again after failure. CaP-X and τ₀-WM do this within an attempt. ENPIRE and GaP extend it across trials. The cost is harsher than in language. Search delays action, while physical experiments use wear, energy, resets, supervision, and safety budget.
Feedback helps locate failures. A completed command can still miss the goal. Images, controller state, contact signals, errors, and outcome receipts give information about what happened. I recommend that an IK rejection does not cause a goal rewrite. I also recommend that an ambiguous goal does not cause a VLA to retry forever.
Learned priors make proposals better. Predictive models rank them, agents compose them, and traces help diagnose the result.
Success rates depend on resets, initial-state variation, intervention, speed limits, termination rules, and whether partial progress counts. I recommend that evaluations give the actual held-out conditions: embodiment, API, object distribution, physical skill, or composition. I also recommend that researchers publish prompts, traces, controller contracts, failure videos, cost, and intervention rules. Cross-layer orchestration and inference-time adaptation clearly become better. But absolute reliability stays specific to the task, interface, and execution budget. Lima et al. describe agentic robot control as flexible but still fragile.
Request checks before motion
You can usually undo a failed click. A failed grasp can drop glass, deform a part, spill liquid, or move the scene outside the camera’s view. Trial and error make a reset and recovery method necessary, with permission to continue.
The physical world also has no universal accessibility tree. A robot receives incomplete images, noisy depth, occlusion, calibration error, and platform-specific proprioception. Construction of structured state is necessary. That state may already be stale when an action starts.
Robot access adds physical risk to familiar digital risks: an agent can leak data, buy the wrong item, damage property, or injure a person. Prompt injection, compromised sensors, a hallucinated affordance, or stale state can affect motion. Thus, the supply of an actuator API is a permission decision.
Robot evaluations usually give information about task success. Deployment also depends on how failures occur. Suppose one system succeeds 95% of the time and stops safely in other cases. A system that succeeds 99% but occasionally applies force in an incorrect location is a different product.
The relevant risks enter at every layer:
| Where failure enters | Typical mechanism | Physical consequence | Engineering response |
|---|---|---|---|
| Observation and state | Occlusion, calibration error, stale frames | Action targets a scene that no longer exists. | Timestamped state, multi-view and contact checks |
| Identity, goal, and security | Ambiguity, wrong principal, prompt injection | A valid skill serves the wrong goal or user. | Authentication, provenance, capability scopes, confirmation |
| Planning and learned motion | Bad affordance, world-model error, OOD action | Collision, spill, excessive force | Typed skills, critics, receding horizons, action envelopes |
| Timing and control | Cloud delay, stale command, dropped packet | Late correction or uncontrolled continuation | Local watchdog, expiry, force limits, hardware stop |
| Verification and learning | False success, bad reset, unsafe memory | Wrong reward or propagated failure | Independent checks, retry budgets, promotion gates, rollback |
| Fleet and operations | Correlated trials, policy spread, hidden intervention, surveillance | Wear, unsafe rollout, privacy loss, false confidence | Canaries, signed artifacts, budgets, retention rules, public traces |
The same properties that make agents useful increase risk. A model can read the web, write code, and call robot tools. It can connect a malicious label, QR code, skill description, or memory entry to an actuator. Record who supplied data and which user requested the action. Give robot tools narrow permissions even when the agent can read broadly.
Reuse causes correlated failure. One frame-convention bug or unsafe recovery can spread through a skill library or fleet. ENPIRE's reset loop, ASPIRE's memory, and GaP's graph rehearsal make the verifier part of the control system. A false success can promote a brittle policy. Thus, independent reproduction, non-regression tests, signed artifacts, staged rollout, and rollback are necessary for discovery.
Persistent perception adds privacy and audit risks. Video, audio, maps, identities, and physical demonstrations show more than the immediate task. A modular incident spans the agent, planner, vendor policy, and controller. Retention limits, access logs, visible recording state, and an end-to-end decision trace are architectural requirements.
Measure what the planner can do separately from what it is permitted to run.
Each step—from input to plan, request, policy output, and controller command—must have a check independent of the model that proposed it.

Instructions can guide an agent toward safer choices. They cannot make unsafe motion impossible.
Google DeepMind's ASIMOV-Agentic evaluates several capabilities of a reasoning agent. The tests examine whether the agent refuses actions that violate operational constraints. The tests examine whether the agent triggers protective stops during faults or unsafe proximity to a person. The tests examine whether the agent shields a VLA from infeasible or out-of-distribution requests. The tests examine whether the agent asks for help when instructions or scenes are ambiguous.
These semantic capabilities are above the mechanisms that enforce speed, force, workspace, and collision limits.
Physical Agentic AI gives a sharper architectural result. Its foundation-model planner proposes robot-skill assignments. A deterministic orchestrator does checks of one dispatch at a time against capabilities, state, and workflow rules. Retrieval increased skill grounding from 51% to 96%.
But informed planners continued to attempt faulted actions in 23–29% of steps with the study's injected-fault conditions. Per-dispatch enforcement decreased false dispatches to zero without false blocks in that evaluation.
This result separates planning quality from permission checks. A better model can propose fewer bad actions. Deterministic rules select which proposals may become motion. That gate alone cannot solve robot safety.
I therefore recommend these parts for a credible robot-use stack:
- Typed, capability-scoped tools rather than arbitrary actuator access
- Fresh state plus local speed, force, workspace, and proximity limits
- An explicit outcome check and bounded retries after each skill
- An independent interrupt path, watchdog, and hardware stop
- Traceable decisions and human takeover outside the permitted envelope
Safety depends on the whole path from proposal to motion, including hardware protection, not just instructions in a system prompt.
Reusable skills and teaching traces
Robot learning usually scales through data and policies: more demonstrations, broader model training, added embodiments, and fine-tuning for deployment. That recipe will continue. A strong VLA can compress physical experience into a responsive local policy, and the human-to-robot interfaces used to make such data become better quickly.
Robot-use agents add a different scaling unit: the skill contract.
A skill contract gives the operation, accepted observations and parameters, necessary starting conditions, completion test, reported failures, and physical limits. A general agent can then discover, compose, repair, and reuse the skill, and do tests of it. A VLA, world model, grasp planner, calibration routine, or teleoperator can all supply that contract's implementation.
Physical prompting adds a second unit: the teaching trace. A deployment can supply more than code or weights. A short demonstration from a verified source can set the context for a broad policy. Reusable traces can contain what language specifies poorly—contact sequence, grasp style, or bimanual timing. Typed contracts give permissions and completion criteria. Code, demonstrations, and weights become complementary forms of robot software.
Reusable skills change where engineering effort compounds. A better controller makes each task that calls it better. A better perception tool makes each agent that reads its state better. A validated recovery routine becomes part of a shared library. A stronger frontier model can attempt new compositions without new demonstration collection for each sequence.
Disciplined robot APIs, evaluations that show physical failures, and safety systems that expect planner mistakes continue to be necessary for reusable skills. General agents rely on hardware, robot data, and contact-rich policies.
RoboCurve’s 19/20 block placement and 2/20 insertion show progress alongside a contact-control limit. Capability can come from a better frontier agent, a typed skill, a prompted local policy, or verified experience used in code and weights. If the interfaces become portable, behavior may spread faster than the hardware fleet changes.
When I assess a robot demo, I want to know what the agent could observe and call. I also want to know what happened when it was wrong, and which layer could stop it.
The robot may become another tool for a general agent. The hard part is to make it a tool we can trust.
Appendix: results for each system
This table collects the systems discussed above. The systems have different tasks, robots, budgets, resets, and success definitions.
| Work | Agent interface | Robot-specific training | Feedback and recovery | Real hardware | Main limit |
|---|---|---|---|---|---|
| π₀ family | Images, language, state → action chunks | Multi-robot pretraining plus post-training | Receding chunks, visual feedback | Yes | Substantial action data and embodiment integration |
| Claude Plays Robotics | Direct commands, code, RL, or pretrained policy | Depends on interface | Repeated trials and strategy revision | Yes | Direct joint and humanoid control stay weak. |
| GEN-1.5 | Sensorimotor demonstrations in a 30-second context | Extensive proprietary physical pretraining. None for a one-shot task | 100 Hz closed-loop policy. Some reported recovery | Yes | Company evaluation. 59% ±10% on ten simple, short-horizon tasks |
| Behavior Prompting Policy | One demonstration as a behavior prompt | Diverse prompt pretraining | Closed-loop execution | Yes | Task diversity and embodiment alignment |
| τ₀-WM | Action proposals, predicted futures, ranking | ≈27,300 robot/human hours | Sampling and rectification | Yes, as reported | Plausible video can be physically wrong. |
| VIA | Screenshots and browser-style 3D tools | None for the agent | Observe and adjust each step | No in the reported benchmark suite | A visual interface abstracts away part of real-world dynamics. |
| CaP-X | Programs over perception and control primitives | Training-free agent. Optional CaP-RL | Structured traces, visual differencing, retries | Yes | Reliability depends strongly on designer abstractions. |
| Waddle | Programs, skills, VLAs, robot APIs | No retraining between claimed adaptations | Tests, repair, shared skills | Yes | Vendor stack and task suite |
| ASPIRE | Programs that use a traced execution engine | An agent makes skills from experience. | Failure diagnosis, repair, validation, evolutionary search | Initial transfer evidence | Final success and transfer stay task-dependent. |
| ENPIRE | Coding agents manage reset, verification, rollout, and policy improvement. | An agent can change heuristics, training code, BC, or RL policies. | Automated physical trials and verified rewards across up to eight stations | Yes | The reported 99% is on selected tasks with a fixed eight-retry protocol. Bad resets or verifiers corrupt the research loop. |
| GaP | Graphs from 51 initial MORSL skills | Agents refine the graph and parameters. | Simulation, node checks, edge execution | Yes | New eight-task suite. Large skill scaffold |
| OpenETA | In one configuration: observe, mark_point, and move_to |
No task-specific policy or VLA in that configuration | One world-changing call, fresh observation, trusted receipts, replay | Interface integration only | Pass@5 measures task coverage across seeds, not reliable episode success. No audited robot task rate |
| Harness VLA | Frozen VLA beside analytic tools | No VLA fine-tuning. Memory guides operation. | Re-ground, re-stage, retry | No reported hardware benchmark | Frozen-VLA support ceiling |
| Pigey | A VLM routes short subgoals to π₀.₅ or a TAMP grasp planner. | No new data or post-training for the frozen backends | Visual verification, replanning, backend routing, recovery | Yes | Partial observability can cause false success. Frontier-model calls add latency and cost. |
| Gemini Robotics ER 2 | Typed tools, search, VLA, robot APIs | Embodied-reasoning post-training | Video monitoring, replanning | Yes | Delegates motor execution |
| RoboCurve | Camera views, state, and Cartesian pose commands through IK | No disclosed robot fine-tuning in the evaluation | Up to 20 agent calls | Yes | 95% on simple placement, 10% on precise insertion |
Orchestration: result and deployment notes
OpenETA is the clearest VLA-free example among the new papers. In its Codex configuration, the planner receives only three embodied operations: observe supplies selected views. mark_point converts image selections to a 3D target. move_to previews or executes a gripper motion. After any world-changing call, a fresh observation is necessary for the interface.
Perception, projection, motion, gripper behavior, and the simulator continue to do substantial work. “VLA-free” gives information about these tools. Perception and control continue to assist the VLM.
Two denominators behind the headline result
Two denominators are necessary for the headline result. With GPT-5.6 Sol, the system solved 92 of 130 LIBERO tasks on the first ordered seed. It covered 117 of 130 at Pass@5 (defined above). That coverage is not a 90% episode success rate.
A separate frozen evaluation used 40 tasks and ten seeds each. OpenETA recorded 56 successful episodes out of 400, with at least one success on 18 of 40 tasks. Its real-robot backend reached interface-level integration only, and no self-evolution candidate passed the promotion gate. A stronger planner used the same small interface more effectively. Reliable repetition stayed much less easy.
VLM–VLA hybrids start from a complementary observation. Analytic tools excel at staging, geometry, and explicit constraints. Learned policies are useful for irregular grasps and contact-rich motion.
Harness VLA, from Chao Yu's group and collaborators, treats a frozen VLA as a retryable contact primitive. The outer agent controls re-grounding, navigation, transport, release, and re-staging. Its v4 report gives gains of 38.6 percentage points on LIBERO-PRO and 27.1 points on RoboCasa365, plus 58.4% on RoboTwin clean-to-randomized transfer. These are separate benchmarks. With the VLA frozen, the gain measures orchestration and memory within its existing skill support.
Pigey, from Liane Galanti, Dhruv Shah, and Tri Dao, makes the controlled comparison sharper. A frontier VLM sends concrete subgoals to either a frozen π₀.₅ policy or a TAMP grasp planner, then does checks of progress and recovers. The robot, cameras, scene, demonstrations, and policy weights stay fixed between the direct and agentic conditions. Across six LIBERO-PRO perturbation suites, mean success rises from 12.8% to 53.3%. On 30 real-robot tasks, gains concentrate in reasoning-limited categories—world knowledge, conditionals, multi-step behavior, and recovery—while easy pick-and-place changes little. Frozen policies that were near zero on those reasoning-limited tasks reportedly exceeded 90% inside the loop.
The authors use the name orchestration gap for this difference. It compares what the frozen skills achieve alone and inside the agent loop. Motor weights stayed fixed. Thus, the gain is neither new dexterity nor free intelligence.
Pigey still relies on competent backends, repeated vision calls, and a verifier vulnerable to occlusion. Seven tested reasoners showed the effect. But frontier-model latency and cost keep this loop outside high-speed control. The outer loop makes more of those existing skills usable.
Programs, libraries, and policy improvement: result notes
CaP-X shows this second loop: the action is executable code, and the environment supplies enough structure for repair. Waddle packages the pattern as a persistent system whose agents write control programs, call learned policies, examine runs, and keep validated routines. In one LEGO example, the agent also repeats trials, collects data, and trains an ACT policy. Here it helps to make a skill as well as select one.
ASPIRE turns the loop into a continual-learning architecture. It records per-primitive multimodal traces, diagnoses failures, validates repairs, and keeps successful fixes as reusable skills. Its accumulated library had 31% average zero-shot success on held-out LIBERO-PRO Long tasks, versus 4% for the cited prior methods. Simulation-discovered skills also decreased real-robot debugging effort. Each rollout can supply a reusable procedure.
ENPIRE, a collaboration among researchers at NVIDIA, CMU, and UC Berkeley, moves this research loop onto a physical fleet. Eight bimanual YAM stations repeat a process. They reset a task, do checks of it, deploy a candidate, and collect reward and logs. Then coding agents change heuristics, tool calls, behavior-cloning pipelines, or reinforcement-learning code.
Selected tasks including PushT, organizing pins, and cutting a zip tie reached 99% success with the paper's fixed eight-retry evaluation protocol. That figure belongs to policies developed for those tasks inside a highly engineered autoresearch environment.
ENPIRE’s contribution includes the machinery around that number. For pin insertion, the fleet increases from one agent to eight. With this change, time to near-perfect success reportedly decreases from more than 1.5 hours to roughly 40 minutes. But physical scaling brings idle robots while agents read logs or write code, and superlinear token cost. A flawed reset or verifier can also convert efficient optimization into efficient damage. Outcome checks and physical limits constrain which experiments the research agent may do.
GaP uses a structured method. Agents make, rehearse, and tune a computation graph from 51 initial MORSL skills. Then an edge interpreter runs it. Nodes may include analytic perception, planning, IK, control, and a VLA. Thus, this is not “pure VLM.”
Across four simulated and four hardware tasks, the reported physical results include 25/25 grocery-order trials. They also include 28/30 packing and 18/20 popcorn trials. The custom suite, large skill library, and internal simulation are part of the result and of its reproduction burden.
Google DeepMind's Gemini Robotics ER 2 makes the hybrid split explicit. Its embodied-reasoning model uses video, audio, text, and images. It orchestrates tools, monitors progress, and gives motor execution to a lower-level VLA or robot API. It can reason about the next step while the current action runs. The systems above add a different possibility. The outer agent can collect verified experience and make the tool for its next call better.
Citation
Use this citation:
Ji, Wenbo. “Robot-Use Agents: When Frontier Models Leave the Screen”. fusheng-ji.github.io (September 2026). https://fusheng-ji.github.io/blog/posts/robot-use-agents/
Or use the BibTeX entry:
@article{ji2026robotuseagents,
  title = {Robot-Use Agents: When Frontier Models Leave the Screen},
  author = {Ji, Wenbo},
  journal = {fusheng-ji.github.io},
  year = {2026},
  month = {September},
  url = {https://fusheng-ji.github.io/blog/posts/robot-use-agents/}
}
References
- Phillip Isola, Robot-use agents, September 7, 2026.
- Jay Chooi, GPT-6 Astra robot-control benchmark thread, September 5, 2026.
- RoboCurve, GPT-6 Astra on robotic manipulation, September 4, 2026.
- Vincent Sitzmann, comments on computer-use transfer, training data, and control speed, September 7–8, 2026.
- Anthropic, Claude Plays Robotics, July 9, 2026.
- Hu et al., VIA: Visual Interface Agent for Robot Control, 2026.
- Fu et al., CaP-X: A Framework for Benchmarking and Improving Coding Agents for Robot Manipulation, 2026.
- Lu et al., ASPIRE: Agentic Skills Discovery for Robotics, 2026.
- Waddle Labs, Introducing Waddle: Agents that Control Robots, July 2026.
- Lima et al., Agentic AI for Robot Control: Flexible but still Fragile, 2026.
- Google DeepMind, Gemini Robotics ER 2 and ASIMOV-Agentic, 2026.
- Liu et al., Physical Agentic AI: An Architecture for Orchestrating a Robot Crew with LLMs, 2026.
- Ahn et al., Do As I Can, Not As I Say: Grounding Language in Robotic Affordances, 2022.
- Liang et al., Code as Policies: Language Model Programs for Embodied Control, 2022/2023.
- Huang et al., Inner Monologue: Embodied Reasoning through Planning with Language Models, 2022.
- Generalist Team, GEN-1.5: Embodied Foundation Models are One-Shot Learners, August 19, 2026.
- Black et al., π₀: A Vision-Language-Action Flow Model for General Robot Control, 2024.
- Patel et al., Behavior Prompting Policy: Demonstrations as Prompts for Manipulation, 2026.
- Zhou et al., τ₀-WM: A Unified Video-Action World Model for Robotic Manipulation, 2026.
- Xiao et al., ENPIRE: Agentic Robot Policy Self-Improvement in the Real World, 2026.
- Chen et al., GaP: A Graph-as-Policy Multi-Agent Self-Learning Harness for Variational Automation Tasks, 2026.
- Chen et al., ETA: A New Agentic Paradigm for Embodied Tasks, 2026.
- Zhang et al., Harness VLA: Steering Frozen VLAs into Reliable Manipulation Primitives via Memory-Guided Agents, 2026.
- Galanti et al., Addressing the Orchestration Gap in Generalist Robots via Physical Agency, 2026.
Note: This blog was written and polished with the assistance of Codex (GPT-5.6 Sol).
Updated